Celtic Constellation
Traditional mouth-blown smallpipes producing a sweet, mellow tone ideal for expressive melodic modeling and Celtic generative tasks.
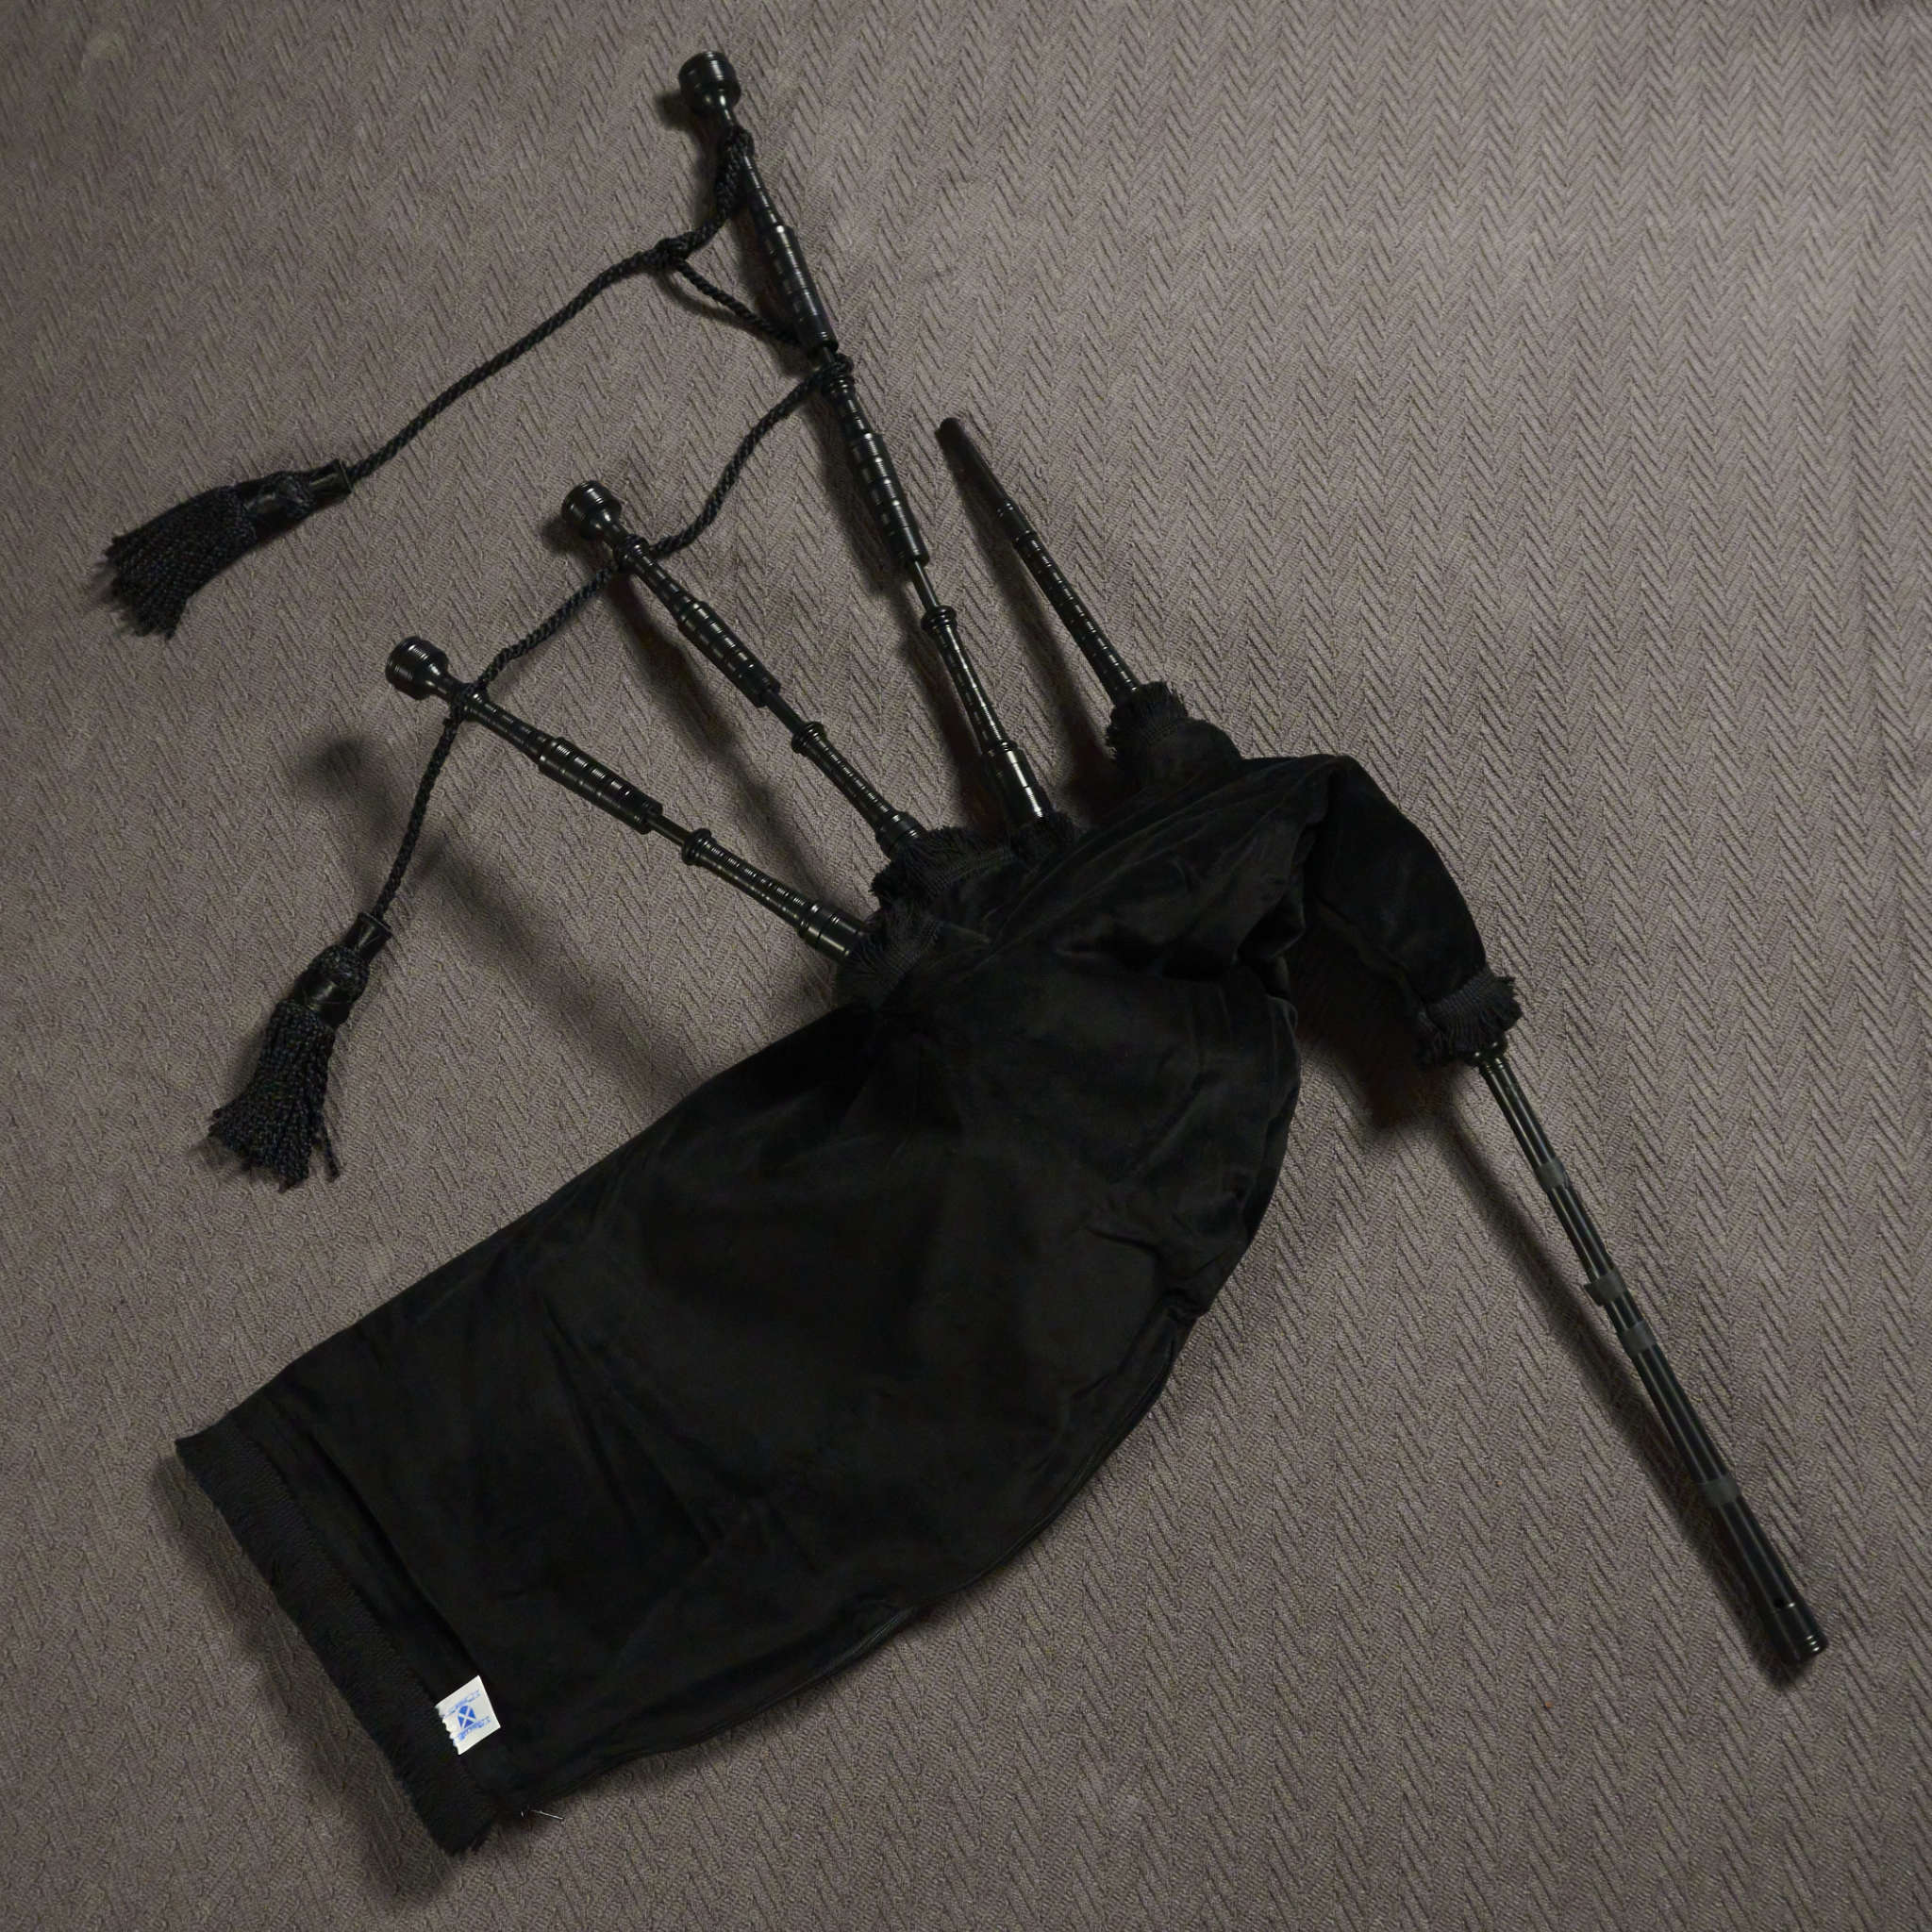
Scottish smallpipes are a form of bagpipe featuring an open-ended chanter and a continuous airflow-driven sound production system. In this dataset, the instrument is a mouthblown set of smallpipes, in which airflow is supplied directly by the performer rather than via bellows. This configuration introduces natural breath-driven variation while maintaining a relatively stable tonal output, with expressive control emerging primarily through fingering technique, articulation timing, and breath pressure management rather than large dynamic shifts.
Acoustically, modern Scottish smallpipes occupy a focused and consistent timbral space, with smooth note transitions and a comparatively restrained dynamic range relative to other reed instruments. Expressivity is conveyed through articulation patterns, gesture timing, and ornament-driven movement rather than abrupt changes in amplitude or timbre. Traditionally used in Scottish folk and ensemble contexts, the instrument’s physical design and continuous airflow characteristics make it well suited for articulation-level analysis and modeling, where clarity of note transitions, pressure stability, and repeatable gesture behavior are important.
Key technical details for this dataset — including file counts, duration, delivery format, and session context.
Planned technical specifications and recording standards for this dataset.
Total Files:
Total Files (Preview):
13
Sample Rate (Hz):
96000
Bit Depth (Delivery):
24
Dataset Version:
v0.9
Recording Environment:
Treated Studio
Microphone Configuration:
Rode NT1-A above drones, Oktava MK-012 in front of chanter
Performer:
Blake Pullen
Recording Dates:
Aug. 17th, 2025 (preview subset)
Recording Location:
Las Vegas, NV
Produced using standardized capture, editing, and QC protocols with versioned metadata and Proteus-backed provenance.
This preview includes representative examples of core Scottish smallpipes articulations, captured in isolation to support articulation-aware modeling and analysis.
Articulations include:
Articulations are recorded without accompaniment or rhythmic framing to preserve clarity and separability.
Captured with expert musicians and vocalists across global traditions — ensuring each dataset carries authentic nuance, human expression, and rights-managed provenance.

Blake Pullen is a trained vocalist, Celtic instrumentalist, and recording engineer, and the founder of Harmonic Frontier Audio. He performs and records HFA’s initial datasets to set the capture and labeling standard for the catalog.
A three-part listening benchmark: a mixed musical demo built from this dataset, the raw source clip, and an AI model’s attempt to reproduce the same prompt.
A musical demonstration created by replacing a state-of-the-art AI-generated lead instrument with original source recordings from this dataset, then arranged and mastered to preserve musical context. This approach allows direct comparison between current-generation model output and real, rights-cleared acoustic source material.
Directly from the dataset: an isolated, unprocessed example of the source recording.
An unmodified output from a current-gen AI model given the same musical prompt. Included to illustrate where today’s systems still differ from real, recorded sources.
AI model approximations generated using publicly available state-of-the-art music generation systems.
Harmonic Frontier Audio datasets are licensed directly to research teams, startups, and enterprise partners. Access models and terms vary based on use case, scale, and integration needs.
All datasets are delivered with versioned metadata, documented workflows, and Proteus-backed integrity manifests.
We typically respond to inquiries within 1 day.
This dataset is actively being recorded and prepared. You can request early access, previews, or discuss licensing timelines.
We typically respond within 1–2 business days.